GEO-first brand growth

GEO your brand can prove.

Jincove is the GEO-first growth studio for brands and agencies. We read the six major AI answer engines — ChatGPT, Perplexity, Gemini, Google AI Overviews, AI Mode, and Copilot — and turn raw answers, citations, and sources into the content and creative that get a brand named.

No card. No call. No catch. Reply in 2 business days.

Running scheduled prompts

The engines we monitor — not a client list.
ChatGPTChatGPT
PerplexityPerplexity
GeminiGemini
Google AI OverviewsGoogle AI Overviews
Google AI ModeGoogle AI Mode
CopilotCopilot
ChatGPTChatGPT
PerplexityPerplexity
GeminiGemini
Google AI OverviewsGoogle AI Overviews
Google AI ModeGoogle AI Mode
CopilotCopilot
ChatGPTChatGPT
PerplexityPerplexity
GeminiGemini
Google AI OverviewsGoogle AI Overviews
Google AI ModeGoogle AI Mode
CopilotCopilot
ChatGPTChatGPT
PerplexityPerplexity
GeminiGemini
Google AI OverviewsGoogle AI Overviews
Google AI ModeGoogle AI Mode
CopilotCopilot

Features

Evidence-grade GEO, in one workbench

We audit, monitor and report how AI answer engines treat a brand — with a receipt behind every number.

Mention rate
38%+6%
Named
38%
46 answers
Cited only
22%
26 answers
Absent
40%
48 answers

Cited on 9 answers where the brand went unnamed — that gap is the pitch

Mentioned vs cited, split out

Each answer is checked for two facts: did the engine name the brand, and did it cite its domain. The gaps between the two become the fix roadmap.

ChatGPT
Perplexity
Gemini
AI Overviews
AI Mode
Copilot
Six engines, one record

ChatGPT, Perplexity, Gemini, Google AI Overviews, Google AI Mode and Copilot — queried through a single REST or MCP call, with every answer stored in one record format.

12.5K
Reports in your own stack

Pull runs into your own dashboards via API or MCP, or export client-ready evidence directly. White-label friendly when an agency delivers the report.

Share of voice
34%+5%
Your brand
34%+5.2%
Competitor average
13%-1.8%
From answers to trend lines

Schedule the prompts your buyers actually type. Watch visibility, share of voice and cited sources move week over week.

0

Answers stored

0

Mentioned

0

Cited

ChatGPT
2.5% mentions
ChatGPT
Perplexity
-1.2% mentions
Perplexity
Gemini
4.1% mentions
Gemini
Scheduled runs, on the record

Monitoring re-runs each brand’s buyer questions on a cadence — weekly down to every 15 minutes — and flags a change only when it clears the sampling noise.

g
cited sourceg2.com
×12
r
cited sourcereddit.com/r/SEO
×9
c
cited sourceclutch.co
×7
g
cited sourceg2.com
×12
r
cited sourcereddit.com/r/SEO
×9
c
cited sourceclutch.co
×7
g
cited sourceg2.com
×12
r
cited sourcereddit.com/r/SEO
×9
c
cited sourceclutch.co
×7
g
cited sourceg2.com
×12
r
cited sourcereddit.com/r/SEO
×9
c
cited sourceclutch.co
×7
y
cited sourceyoutube.com
×6
m
cited sourcemedium.com
×5
l
cited sourcelinkedin.com
×4
y
cited sourceyoutube.com
×6
m
cited sourcemedium.com
×5
l
cited sourcelinkedin.com
×4
y
cited sourceyoutube.com
×6
m
cited sourcemedium.com
×5
l
cited sourcelinkedin.com
×4
y
cited sourceyoutube.com
×6
m
cited sourcemedium.com
×5
l
cited sourcelinkedin.com
×4
Answers with receipts

Every run returns the raw answer text, the citations inside it, and the sources behind it. When anyone asks “says who?”, you open the record.

Evidence

Evidence, not a score

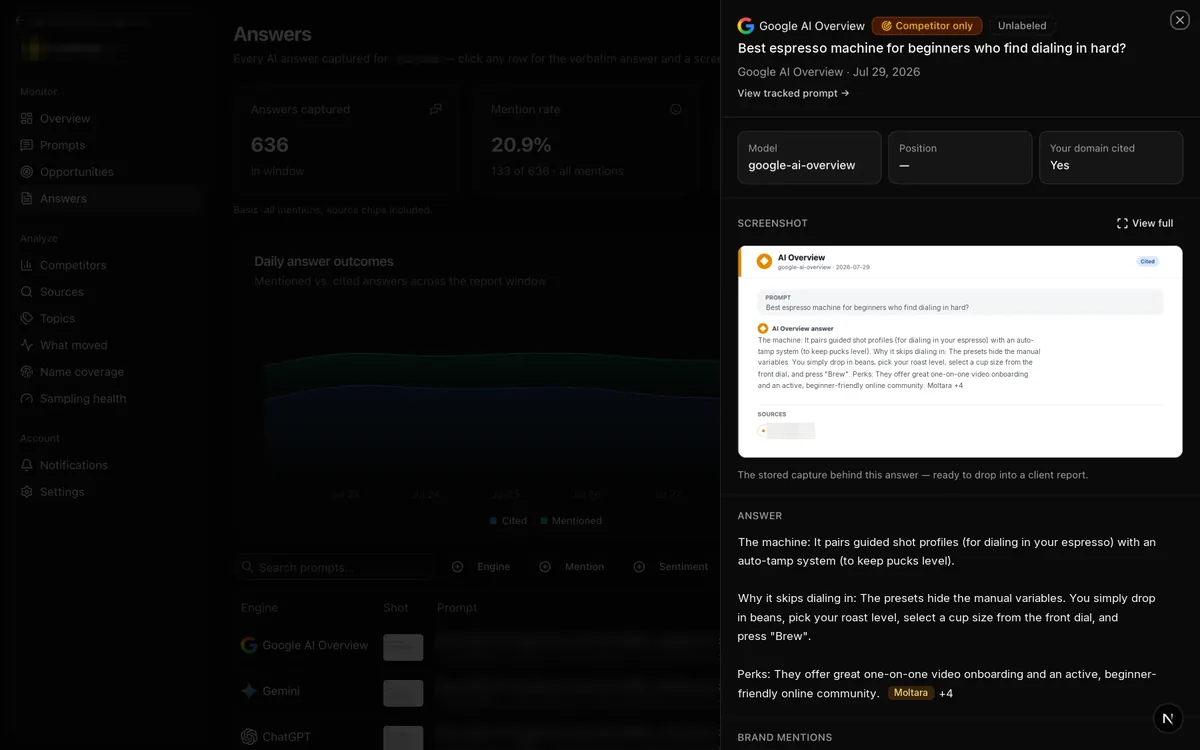
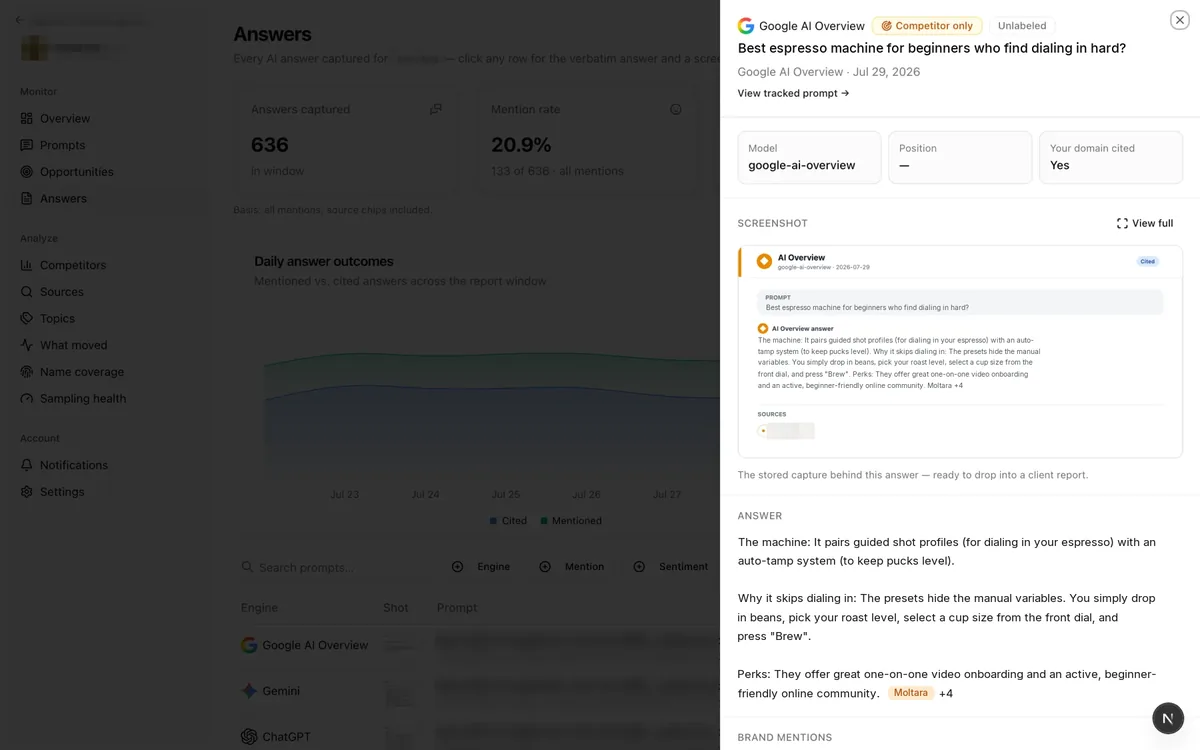
No testimonial wall — here is the deliverable itself. Sample rows, shown the way they appear in a report: the prompt, the engine, the verbatim answer, and every source behind it.

“best home espresso machine for a small kitchen?”

2026-09-05 · scheduled run

ChatGPT

“For small kitchens, the Fervano Uno and Moltara Due come up most often — Fervano is usually recommended for value, with a compact dual boiler that still fits under the cupboards…”

reddit.com/r/espressoseriouseats.comfervano.com
Named ✓

“do I need a PID for consistent espresso at home?”

2026-09-05 · scheduled run

Perplexity

“Yes — PID control holds brew temperature within about ±1°C, which keeps shots repeatable. Typical offsets and warm-up times are covered in this dialing-in guide…” (cites the client’s guide, never names the brand)

fervano.com/guides/dial-inen.wikipedia.org
Cited only

“top espresso machine brands to consider this year”

2026-09-04 · scheduled run

Gemini

“Popular options include Moltara, Cremalio and Tavenne, each offering entry-level dual-boiler machines…” (the gap — this row becomes the fix roadmap)

seriouseats.comtechradar.com
Absent

Illustrative sample data. In a delivered report, every row opens back to the stored raw answer — verbatim text, citations, sources, and provider metadata.

FAQ

Frequently asked questions

How the free sample audit works, what monitoring covers, and where the evidence comes from.
Jincove LLC is an independent studio for GEO-first brand growth. We audit what AI answer engines - ChatGPT, Perplexity, Gemini, Google AI Overviews, AI Mode and Copilot - say about a brand, close the gaps with content, creative production and search work, and re-measure with evidence reports where every row opens to a stored raw answer. We work with brands directly, and agencies use our GEO workbench for their clients.

A human-run audit of ChatGPT, Perplexity and Gemini. Send one URL and one email - no card, no account, no sales call - and we reply within two business days with a mini report: what each engine answered, who it cited, and whether it named the brand. Paid work covers all six engines.

Yes - an LLM audit is the natural entry point for an agency adding GEO. It tells you which buyer questions surface a client, whether the answers name them or only cite their content, and which sources the engines lean on. From there, the audit sets the baseline, monitoring re-runs the same questions on a schedule, and every report row opens back to a stored answer your client can check.

More than once. AI answers drift across time and sampling, so a single snapshot is noisy by nature. Our monitoring re-runs buyer questions on a cadence from weekly down to every 15 minutes, diffs each run against the brand's own history, and reports a change only when it clears the sampling noise band.

No - and we'd be wary of anyone who does. Nobody controls what the engines say. We audit where a brand stands, fix the gaps within reach (or hand your team the list), then re-run the same questions to verify whether the answers moved.

No. Ontology, RAG and grounding work on the input side: they feed your own agents your own business. We work the output side - checking whether external answer engines name a brand and cite its domain. Two booleans per answer, each traceable back to the stored raw answer.

GEO is where most of our work starts. When the audit shows gaps, we also produce the content and creative that close them - articles, comparison and FAQ pages, product images and short video - and run the SEO work alongside, then re-run the same questions to measure what moved.
Jincove evidence drawer - every row opens back to a stored raw answer

See what AI says. Then fix it.

Send one brand. Get the answers, the sources, and the first gaps worth fixing.

No card. No call. No catch. Reply in 2 business days.